4.2. Backpropagate Through the Final Neuron
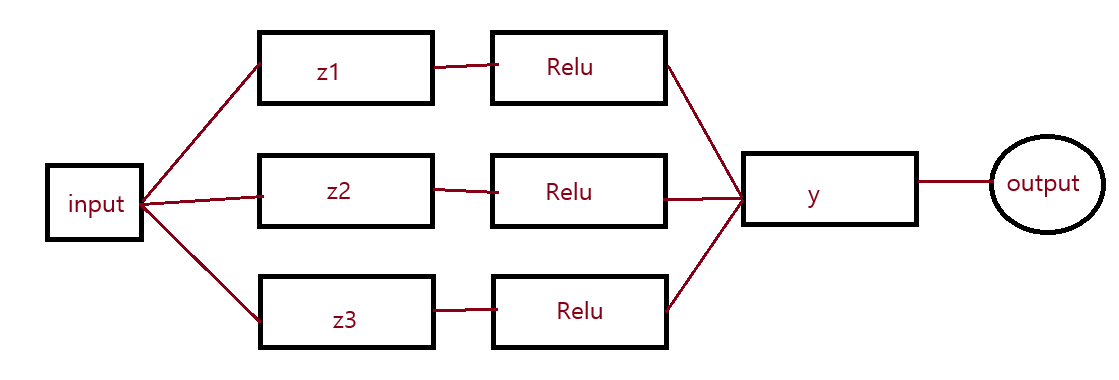
4. Backpropagation
Backpropagation means calculating:
for every weight and bias.
We start at the loss and move backward.
L
↓
y
↓
a1, a2, a3
↓
z1, z2, z3
↓
hidden weights and biases
The chain rule is the main mechanism.
5. Start at the Loss
Our loss is:
Therefore:
Here:
and:
So:
The positive gradient tells us that increasing the prediction increases the loss at this point. The final neuron is:
We need gradients for:
Gradient of w1
Therefore:
Gradient of w2
Gradient of w3
Gradient of final bias
Because:
we get:
7. Continue Backward Through the Hidden Layer
Now we need gradients for:
For :
Therefore:
For :
For :
8. Backpropagate Through ReLU
ReLU is:
Its derivative is:
Our values are:
All are positive.
Therefore:
So:
Similarly:
9. Backpropagate Into Hidden Weights
Neuron 1:
For :
Therefore:
For :
For :
Neuron 2
We have:
Therefore:
Neuron 3
We have:
Therefore:
10. All Gradients
We have now backpropagated through the entire network.
Hidden layer
Final neuron
Every trainable parameter now has a gradient.
11. Weight and Bias Update
Backpropagation gave us the gradients.
Now gradient descent uses them to change the parameters.
The update rule is:
where is the learning rate.
Use:
learning_rate = 0.001
For example:
For :
For :
The same update is performed for every parameter.